AI City Challenge 2025, Track 3 / ICCVW 2025 Workshop (3rd place)
SmolRGPT: Efficient Spatial Reasoning for Warehouse Environments with 600M Parameters
Embia, Computer Science Department, Université de Moncton
 Paper
 Code
SmolRGPT is a 600M-parameter multimodal system for warehouse spatial intelligence: grounded question answering over region masks from RGB and depth images. It took 3rd place in AI City Challenge 2025 Track 3 with an S1 score of 90.68, and it outperforms GPT-4-class models on the qualitative tasks of SpatialRGPT-Bench.
Overview
A warehouse robot that can act on a scene also needs to talk about it: how many pallets sit in the leftmost buffer area, how far one pallet is from another, which side of a transporter an object falls on, and which pallet an empty transporter should pick up next. SmolRGPT is a multimodal system built to answer exactly these spatial questions from RGB and depth images of real warehouse environments.
The system pairs a frozen visual feature extractor (SigLIP2) with trainable connector and refiner modules that process RGB and depth features separately. Region masks select the objects a question refers to, and mask pooling aggregates their features into compact region tokens. Those tokens, together with the question, are fed to a small vision-language model (SmoILM2) that integrates visual and textual information and produces a natural-language answer grounded in the referenced regions.
The bet is efficiency. At 600M parameters the whole system is one to three orders of magnitude smaller than the GPT-4-class and 7B–34B models it benchmarks against, yet it took 3rd place in the AI City Challenge 2025 Warehouse Spatial Intelligence track and beats every model under 7B on SpatialRGPT-Bench's qualitative tasks, a size that makes on-premise, resource-constrained deployment realistic.
Architecture
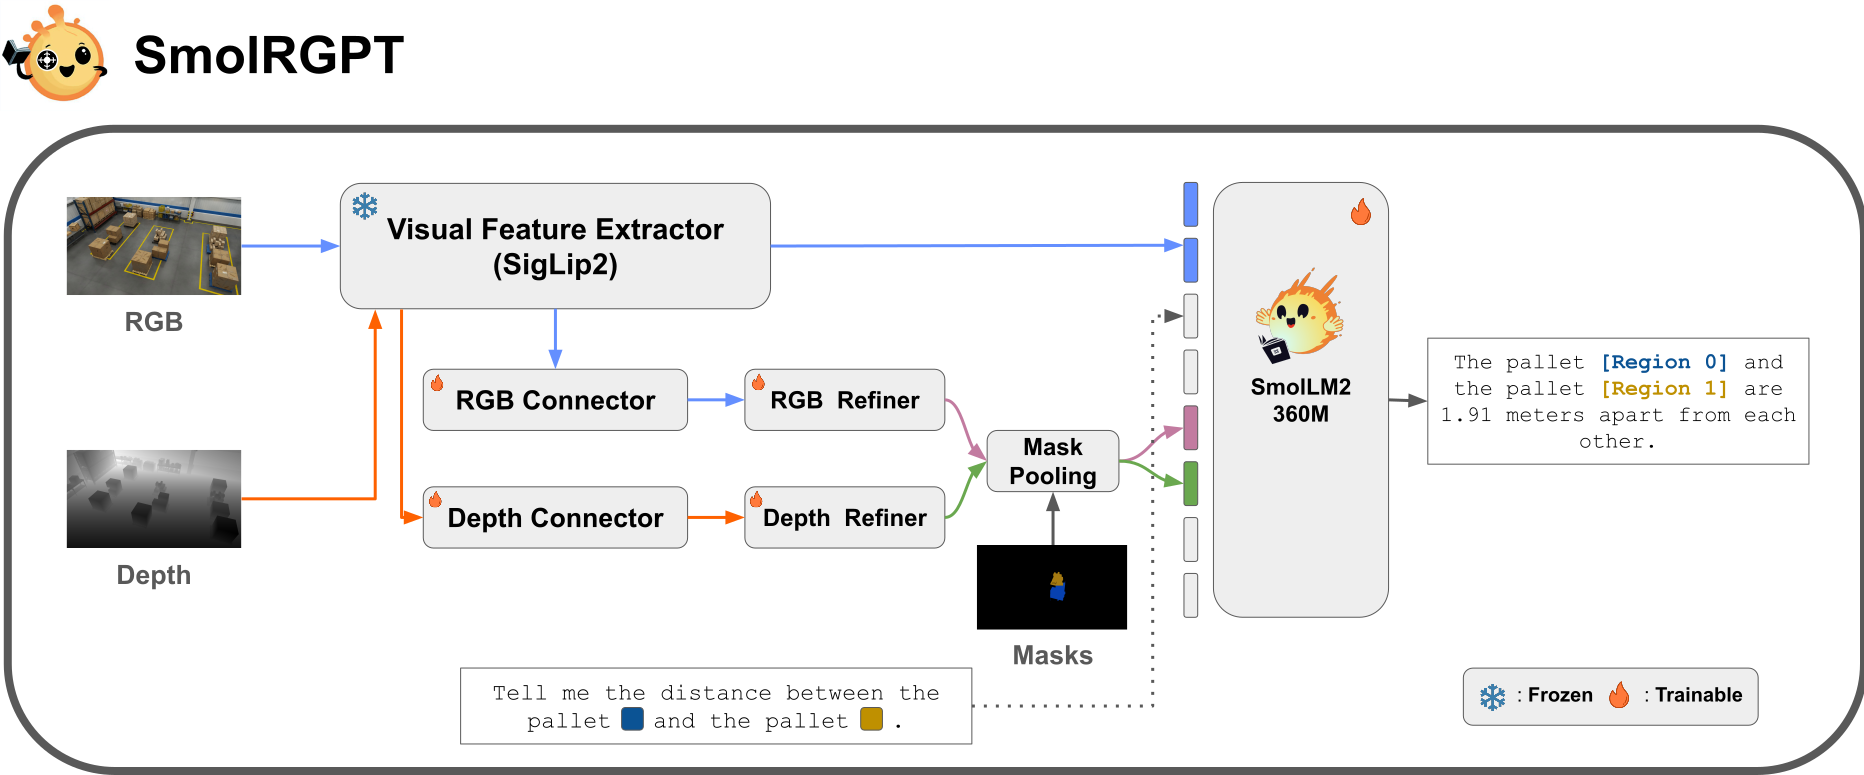
Grounded spatial question answering


AIC 2025 Track 3: Warehouse Spatial Intelligence
SmolRGPT placed 3rd of 9 teams in AI City Challenge 2025 Track 3 with a final S1 score of 90.68, within 1.3 points of 2nd place. The per-task breakdown shows where the small model holds up: 99.8% accuracy on left–right direction tasks, 92.76% on counting (RMSE 0.0750) thanks to the depth refiner, 88.02% on multiple-choice spatial reasoning, and 82.13% on distance estimation (RMSE 0.4740), the hardest task and the one where RGB+depth fusion matters most.
| Rank | Team | S1 score |
|---|---|---|
| 1 | UWIPL_ETRI | 96.08 |
| 2 | HCMUT.VNU | 91.97 |
| 3 | Embia (SmolRGPT) | 90.68 |
| 4 | MIZSU | 73.06 |
| 5 | HCMUS_HTH | 66.89 |
| 6 | MealsRetrieval | 56.64 |
| 7 | BKU22 | 50.37 |
| 8 | Smart Lab | 31.92 |
| 9 | AICV | 28.30 |
Generalizing to SpatialRGPT-Bench
To test spatial reasoning beyond the warehouse, we trained SmolRGPT on a mix of the OSD and Warehouse datasets and evaluated zero-shot-style on SpatialRGPT-Bench. With 600M parameters it reaches a 65.6% qualitative average, ahead of GPT-4 (57.8%), GPT-4V (58.1%), and LLaVA-v1.6-34B (43.9%), and strongest on behind/front (79.0%) and tall/short (74.1%). The 7B SpatialRGPT models score higher overall but at more than ten times the parameter count.
Qualitative spatial reasoning: accuracy (%)
| Method | Params | Below/Above | Left/Right | Big/Small | Tall/Short | Wide/Thin | Behind/Front | Avg. |
|---|---|---|---|---|---|---|---|---|
| GPT-4 | 1.76T | 64.1 | 42.8 | 42.8 | 61.6 | 61.6 | 49.0 | 57.8 |
| GPT-4V | 1.76T | 63.3 | 46.6 | 64.1 | 60.7 | 68.2 | 45.4 | 58.1 |
| LLaVA-v1.6-34B | 34B | 44.1 | 45.7 | 36.7 | 53.5 | 37.5 | 45.4 | 43.9 |
| GPT-4V+SoM | 1.76T | 75.0 | 55.2 | 42.4 | 54.4 | 49.0 | 47.2 | 54.3 |
| LLaVA-v1.6-34B+SoM | 34B | 44.1 | 40.0 | 33.9 | 47.3 | 41.3 | 46.3 | 42.3 |
| Kosmos-2 | 1.3B | 28.3 | 15.2 | 4.7 | 26.7 | 12.5 | 12.7 | 17.0 |
| RegionVILA | 7B* | 30.8 | 47.6 | 35.8 | 44.6 | 35.5 | 49.0 | 40.4 |
| SmolRGPT | 600M | 71.6 | 49.5 | 67.9 | 74.1 | 51.9 | 79.0 | 65.6 |
| SpatialRGPT | 7B* | 99.1 | 99.0 | 79.2 | 89.2 | 83.6 | 87.2 | 89.8 |
| SpatialRGPT-Depth | 7B* | 99.1 | 99.0 | 80.1 | 91.9 | 87.5 | 91.8 | 91.7 |
On the quantitative tasks, SmolRGPT matches or beats the larger models on direct distance (35.8 vs. GPT-4V's 29.7) and direction, while width and height estimation remain the weak spots, the same pattern as on Track 3, where distance was the hardest task class.
Quantitative spatial reasoning: accuracy (%)
| Method | Params | Direct dist. | Horiz. dist. | Vert. dist. | Width | Height | Direction |
|---|---|---|---|---|---|---|---|
| GPT-4 | 1.76T | 21.6 | 11.5 | 33.0 | 52.3 | 48.1 | 34.6 |
| GPT-4V | 1.76T | 29.7 | 25.4 | 33.0 | 51.1 | 68.4 | 43.9 |
| LLaVA-v1.6-34B | 34B | 24.3 | 24.5 | 30.4 | 30.8 | 42.8 | 33.6 |
| GPT-4V+SoM | 1.76T | 25.7 | 22.1 | 33.9 | 45.8 | 62.4 | 54.2 |
| LLaVA-v1.6-34B+SoM | 34B | 12.8 | 20.4 | 11.3 | 9.0 | 7.5 | 11.3 |
| Kosmos-2 | 1.3B | 4.1 | 4.9 | 18.9 | 3.0 | 3.1 | 3.8 |
| RegionVILA | 7B* | 22.3 | 24.6 | 17.9 | 36.8 | 49.6 | 35.5 |
| SmolRGPT | 600M | 35.8 | 18.3 | 33.9 | 18.1 | 20.3 | 35.5 |
| SpatialRGPT | 7B* | 35.1 | 59.0 | 53.8 | 51.9 | 54.9 | 95.3 |
| SpatialRGPT-Depth | 7B* | 41.2 | 65.6 | 51.9 | 49.6 | 57.9 | 95.3 |
Examples
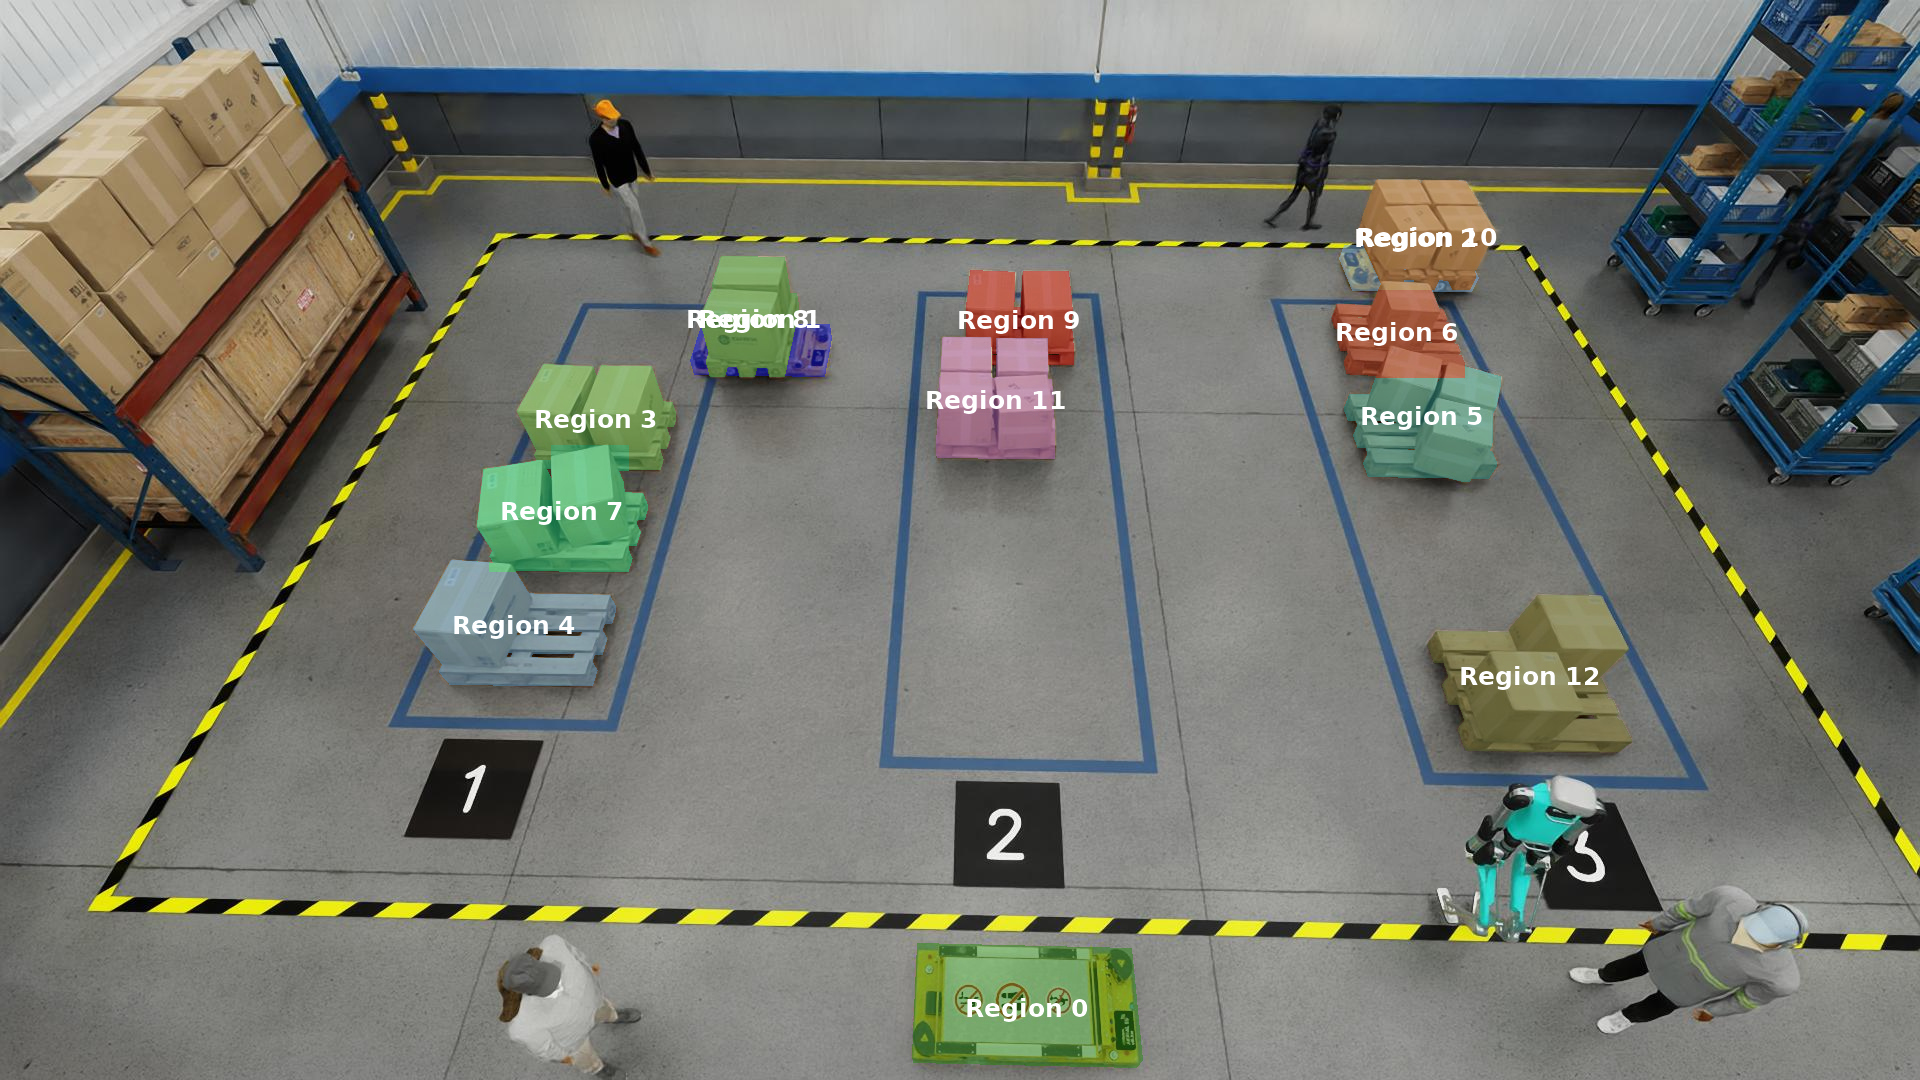
Four task types from the warehouse benchmark (counting, distance estimation, left–right relations, and multiple-choice grounding), each shown with the masked frame, the question, SmolRGPT's prediction, and the ground truth.
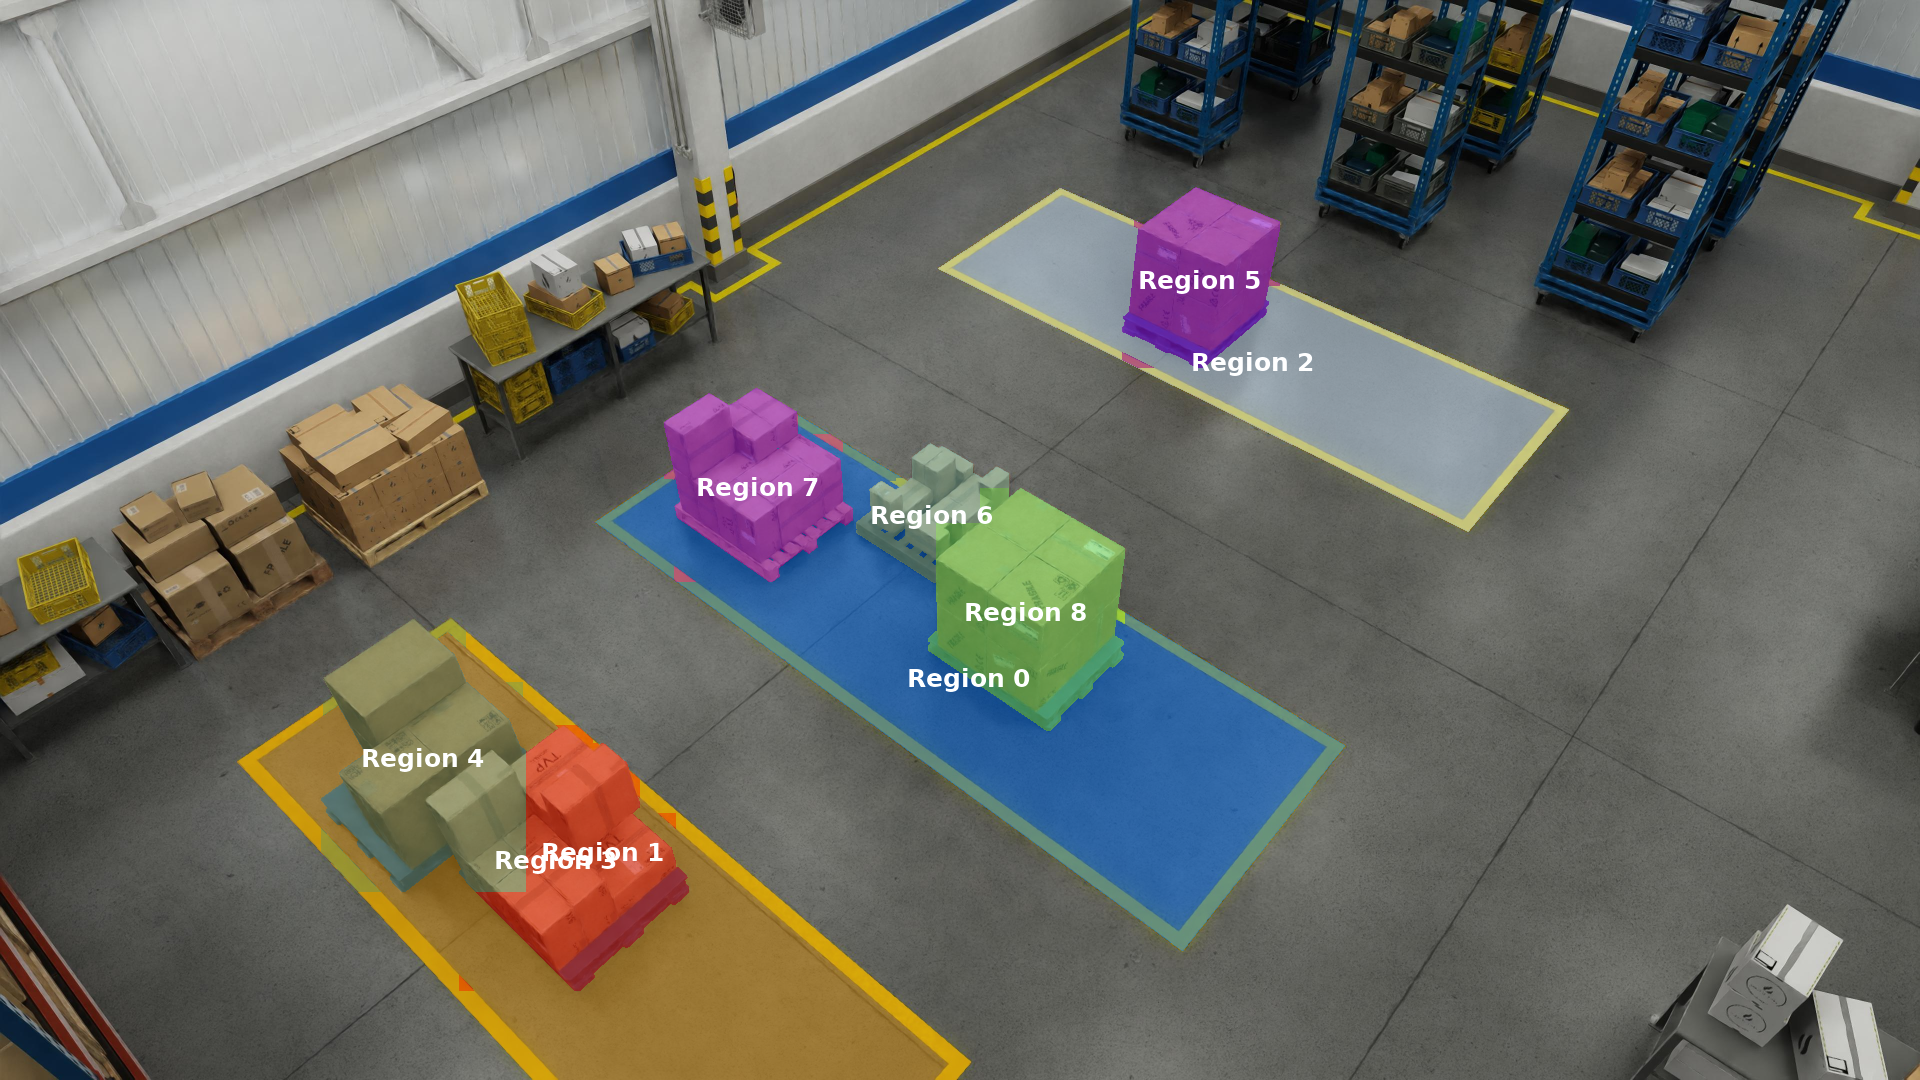
QGiven the buffer masks Region 0 Region 1 Region 2 and pallet masks Region 3 Region 4 Region 5 Region 6 Region 7 Region 8, what is the count of pallets in the leftmost buffer area?
AThe buffer region Region 1 is the leftmost buffer region from this viewpoint. The buffer region Region 1 contains pallets Region 3 Region 4. Therefore, the buffer area Region 1 has two pallets.
GTObserving from this perspective, the buffer region Region 1 is the leftmost buffer region. The buffer region Region 1 has pallets Region 3 Region 4. Hence, in buffer area Region 1, there are exactly two pallets.
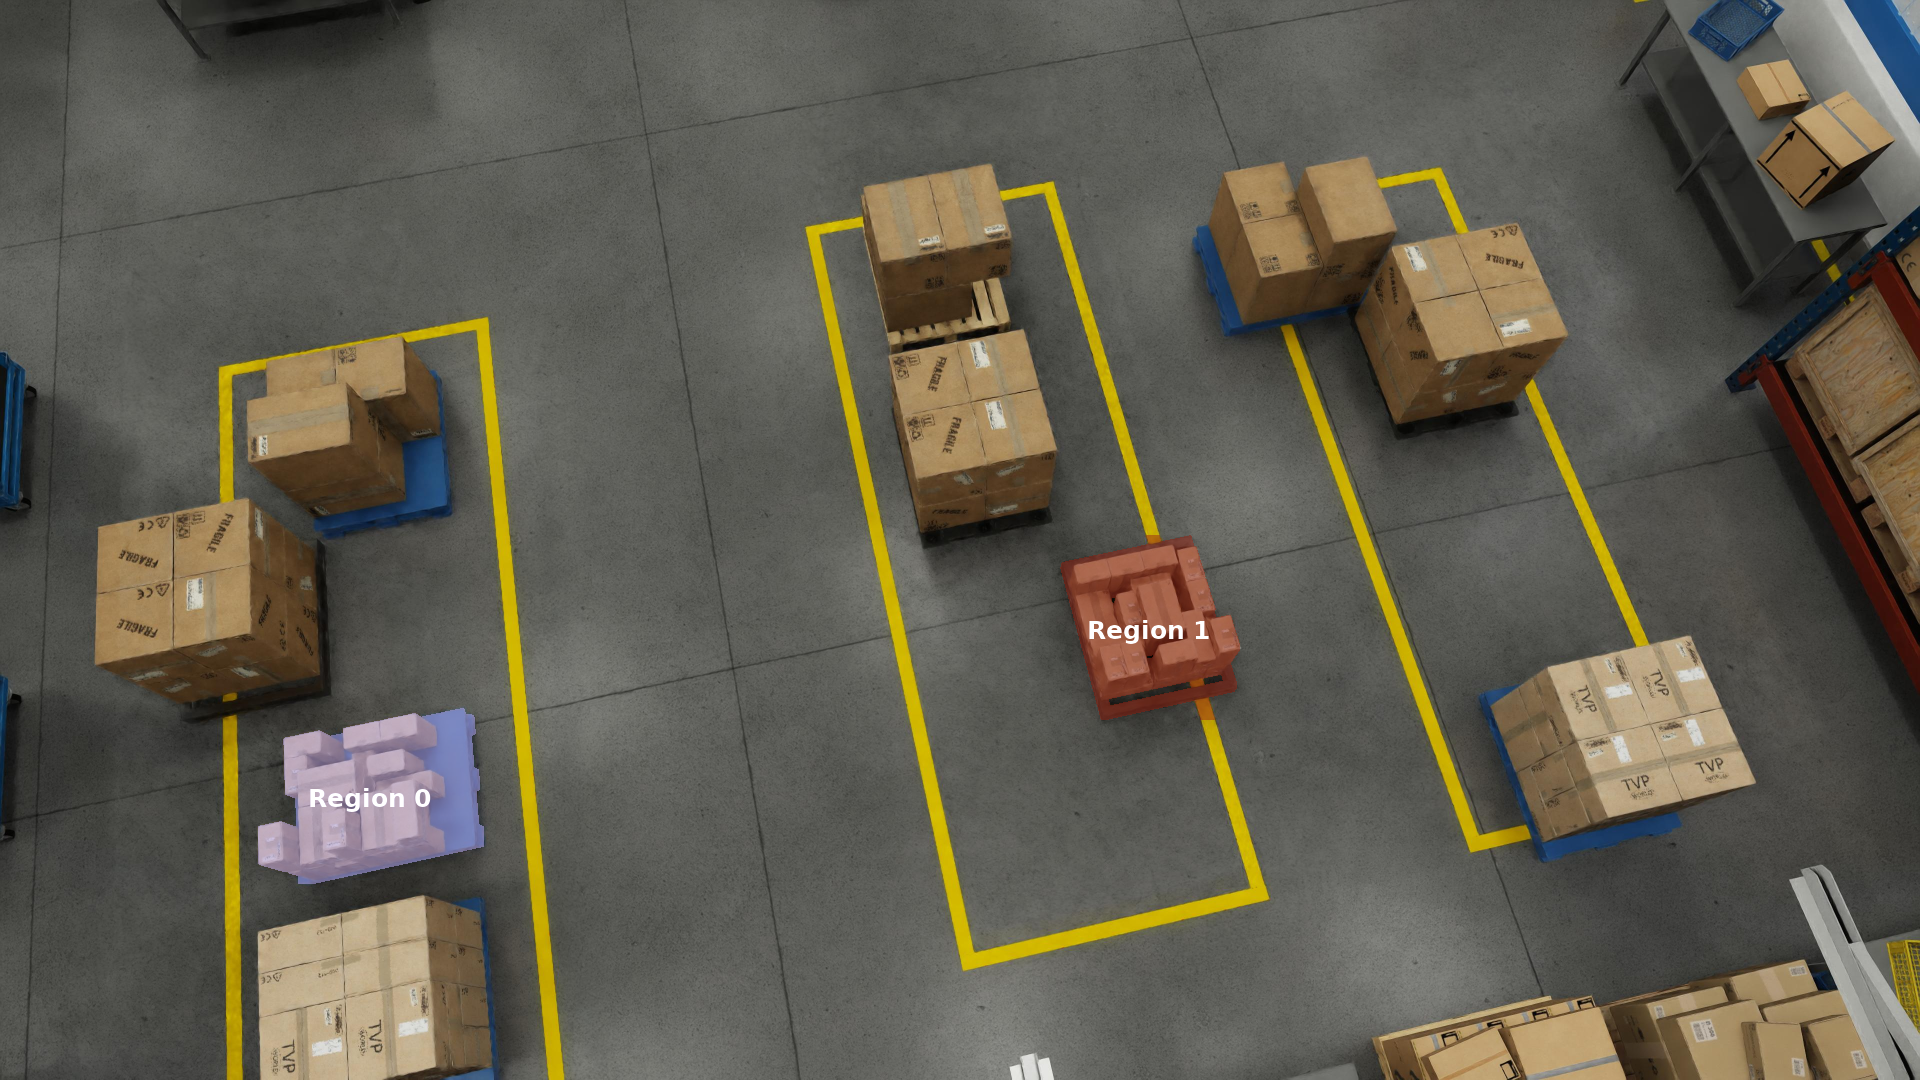
QIs the pallet Region 0 positioned on the left or right side of the pallet Region 1 relative to the observer?
AThe pallet Region 0 is to the left of the pallet Region 1.
GTThe pallet Region 0 is situated on the left of the pallet Region 1.
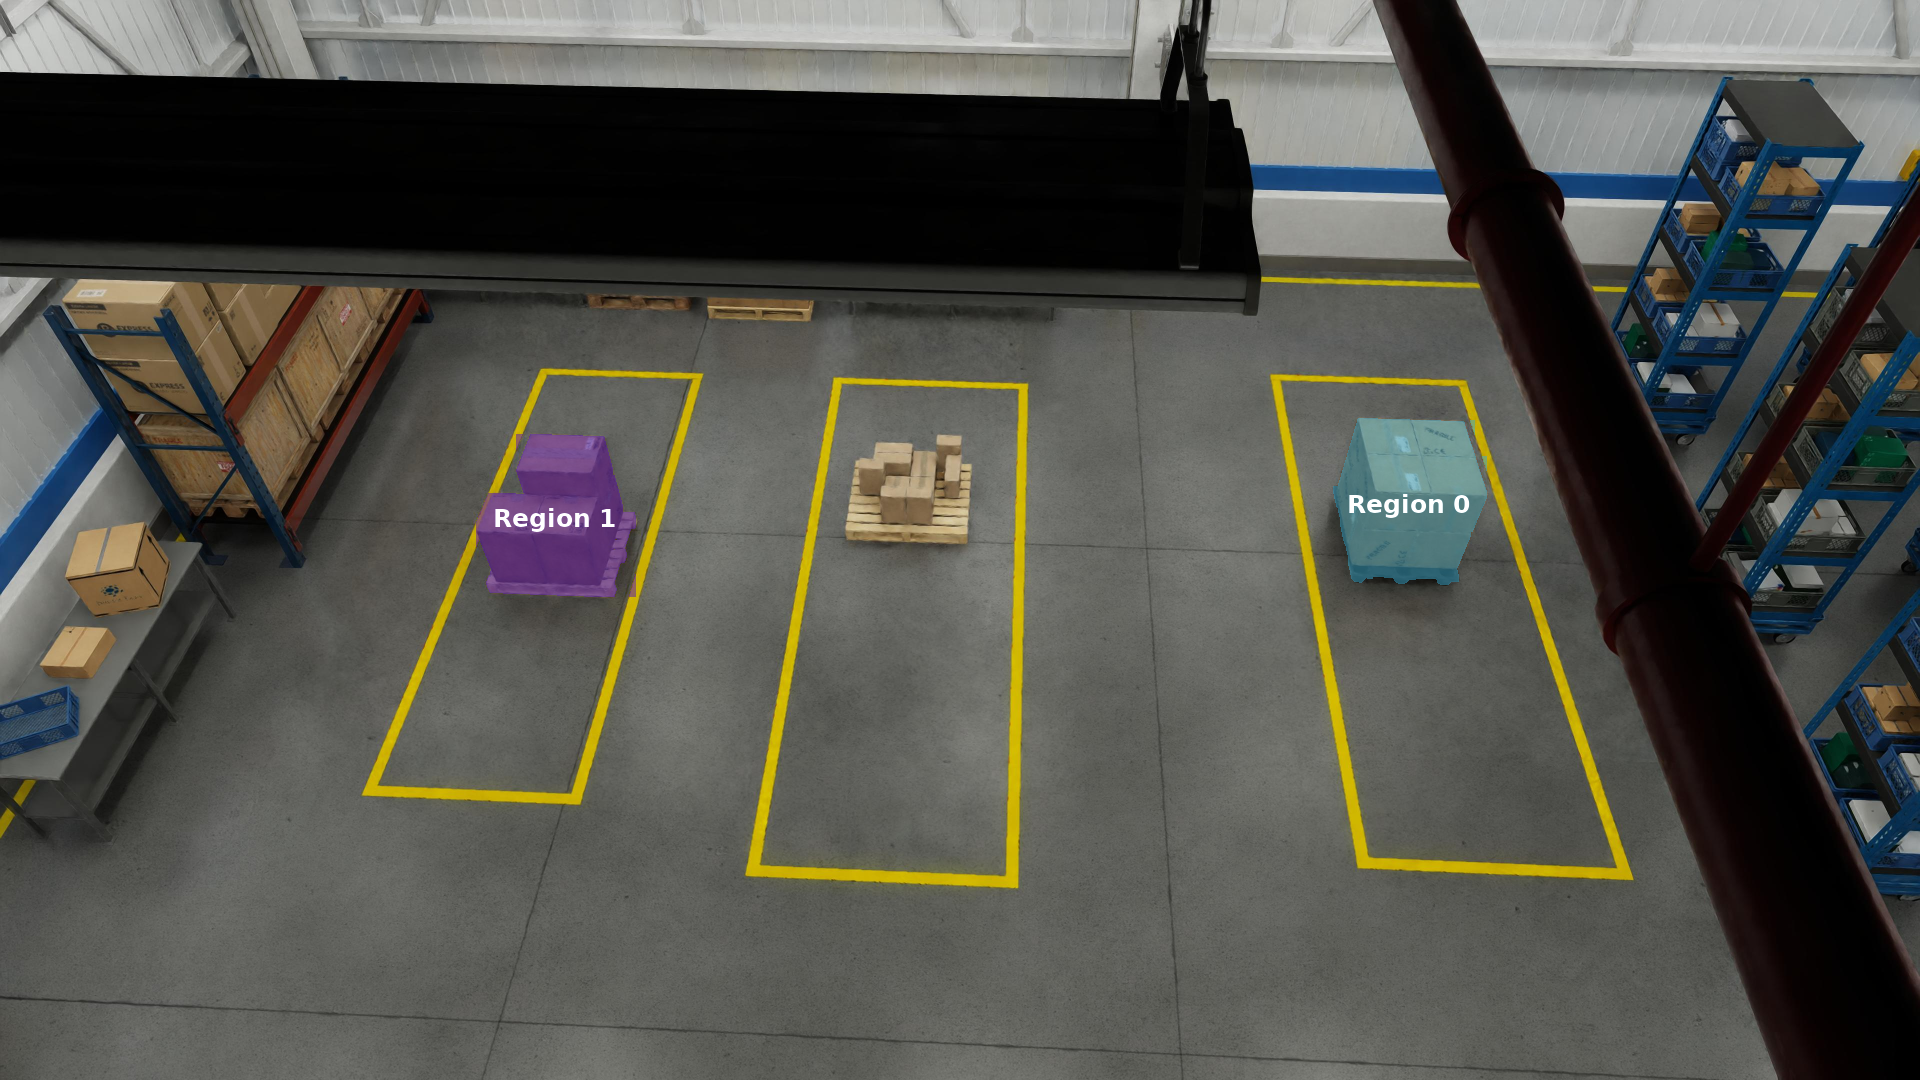
QCould you measure the distance between the pallet Region 0 and the pallet Region 1?
AThe pallet Region 0 and the pallet Region 1 are 8.23 meters apart.
GTThe pallet Region 0 is 8.15 meters away from the pallet Region 1.
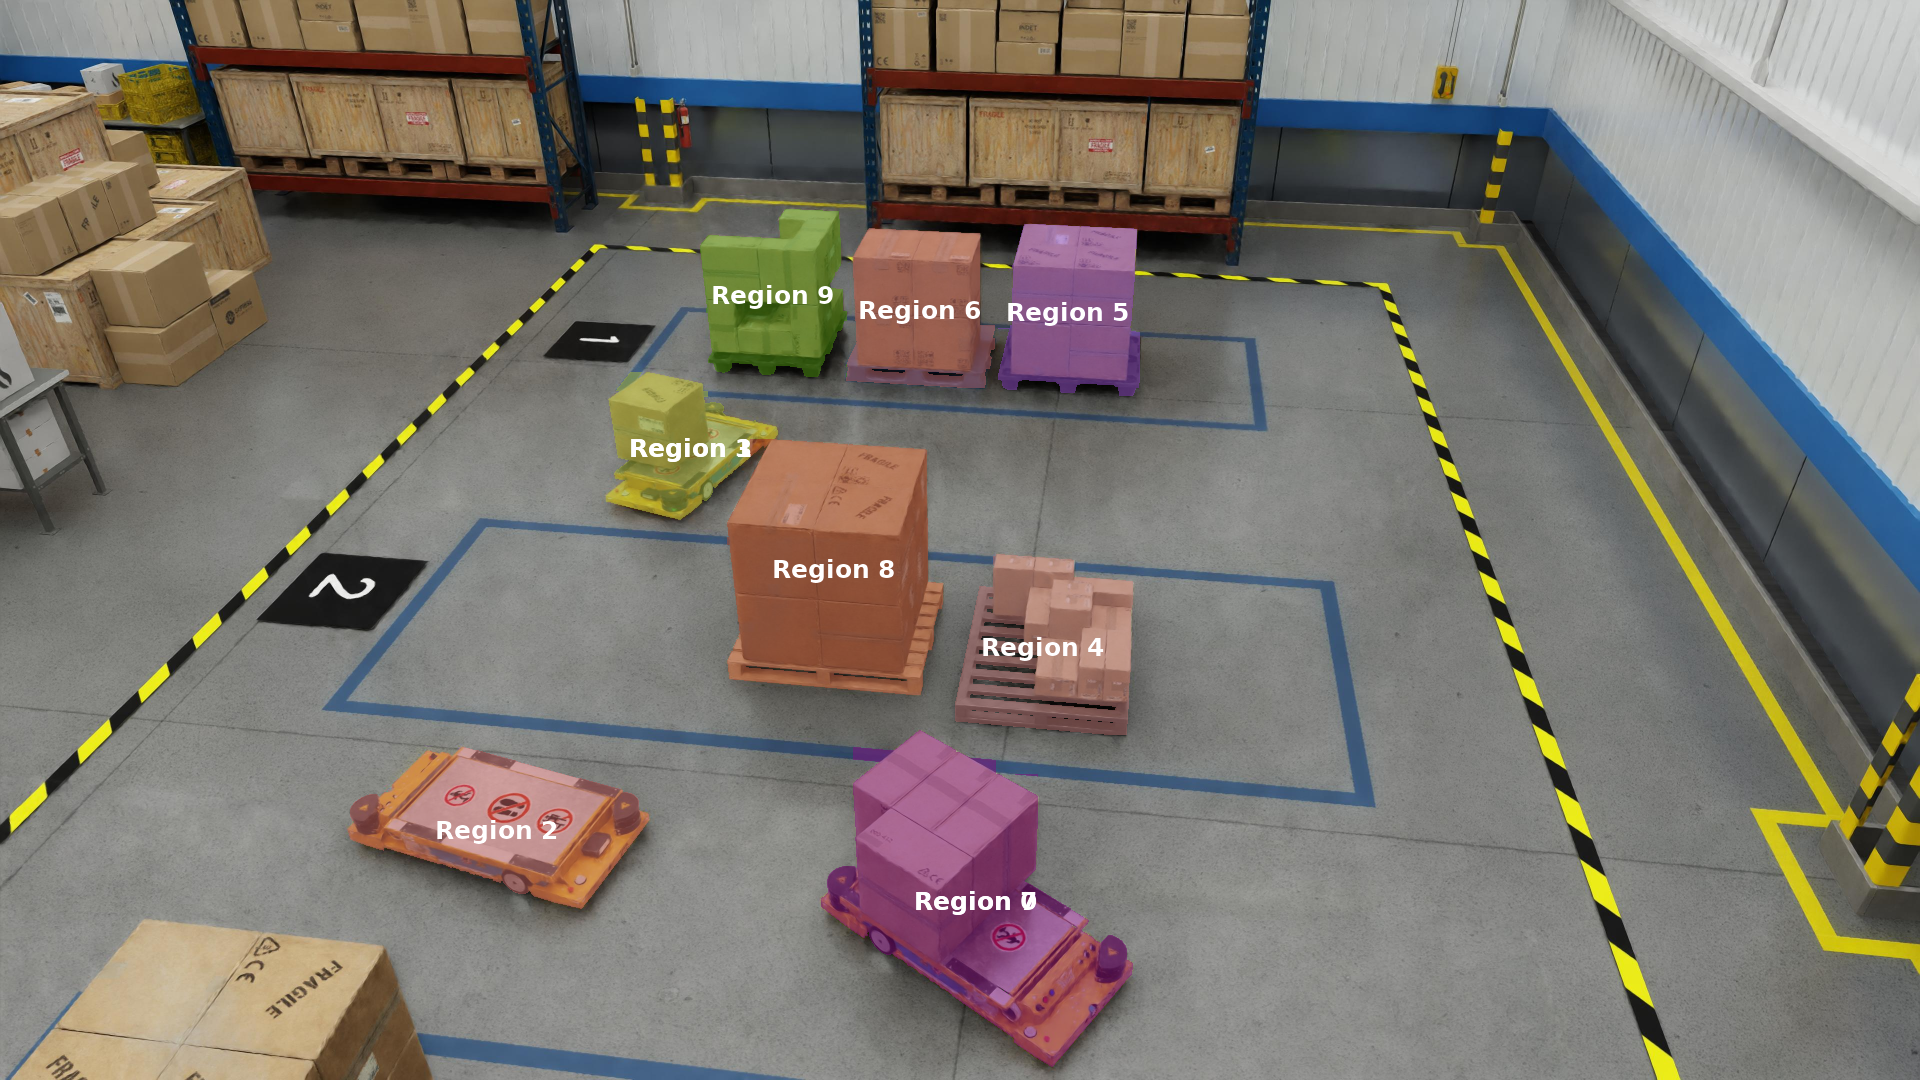
QGiven the transporters Region 0 Region 2 and the pallets Region 3 Region 4 Region 5 Region 6 Region 8 Region 9, which pallet is best suited for automated picking by an empty transporter?
AThe transporter Region 2 is not holding any boxes. The pallet Region 8 is the closest to transporter Region 2, so it is the most suitable choice for automated picking.
GTAt the moment, the transporter Region 2 is not loaded with any boxes. The pallet Region 8 is nearest to the transporter Region 2, making it the best choice to pick up first.
Takeaways
A 600M-parameter system can sit at the top of a warehouse spatial-intelligence leaderboard: 3rd of 9 teams in AIC 2025 Track 3 at 90.68, and ahead of every sub-7B model, as well as GPT-4 and GPT-4V, on SpatialRGPT-Bench's qualitative tasks. The remaining gap to the 7B SpatialRGPT models is concentrated in the fine-grained quantitative estimates.
Depth is what makes the quantitative tasks work. Separate RGB and depth refiners over a shared frozen SigLIP2 backbone drive the 92.76% counting accuracy (RMSE 0.0750) and the 99.8% left–right accuracy on Track 3, while distance estimation (82.13% on Track 3, and width/height on SpatialRGPT-Bench) remains the open problem.
Because only the connectors, refiners, and the small decoder train, the whole pipeline stays cheap enough for on-premise, resource-constrained deployment: the point of building a warehouse reasoner at 600M in the first place.
Citation
@article{traore2025smolrgptefficientspatialreasoning,
  title={SmolRGPT: Efficient Spatial Reasoning for Warehouse Environments
         with 600M Parameters},
  author={Traoré, Abdarahmane and Hervet, Éric and Couturier, Andy},
  year={2025},
  eprint={2509.15490},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2509.15490}
}